AI that runs every day, not just in the demo.
We are an engineering company. We build AI systems into the software a business already runs on, put them in front of real users, and then keep them running. We have been shipping and operating production software since 2018, and we run AI products of our own.
The pilot worked and then stopped
A demo on a laptop is not a system. The moment it has to handle real data volumes, real edge cases and real users, the work that was skipped becomes visible all at once.
Nobody owns it after launch
Models change, prompts drift, providers deprecate endpoints and costs move. Without someone accountable for the system in production, quality degrades quietly until people stop trusting the output.
The model was never the hard part
The difficulty is in the data access, the permissions, the retries, the evaluation and the integration with the systems your team already uses. That is normal software engineering, and it is where most AI work fails.
The systems we actually ship.
Not a service menu — the concrete systems we design, build and run in production.
Retrieval over private data
Question answering and search across your own documents, records and internal systems, with permissions enforced and sources cited. Built on Elasticsearch or Meilisearch depending on the shape of the data.
Explore SolutionMCP servers
Model Context Protocol servers that expose your internal data and actions to Claude and other clients through a defined, authenticated interface. We have shipped real MCP servers, not prototypes.
Explore SolutionAgent pipelines
Multi-step processes where a model plans, calls tools, and hands work back to your systems. Each step is logged, retried and bounded, so a failure is visible rather than silent.
Explore SolutionDocument and report generation
Structured PDFs and reports produced from model output on a schedule or on demand. Layout, data and generated text stay separated so the format can change without touching the pipeline.
Classification and enrichment
Automated tagging, scoring, extraction and normalisation applied to incoming records. Runs as queued background work with a review path for the cases the model should not decide alone.
AI features inside your existing application
Drafting, summarising, extraction and assisted content workflows built directly into the product your team already uses, rather than living in a separate tool nobody opens.
From first call to production.
A small number of steps, each ending in something you can look at. No big-bang delivery.
Pick one workflow
We start from a process that runs today and costs someone real time. We define what the system has to produce, what it must never do, and how we will know it is working.
Build a thin slice to production
We build the narrowest version that a real user can use on real data, and we deploy it. Scope grows after something is live, not before.
Harden it
Evaluation sets, guardrails, fallbacks when a provider fails, cost ceilings, logging and human review where the decision matters. This is the part that separates a pilot from a system.
Run it
We monitor output quality, track spend, update models and prompts as providers change, and extend the system as the workflow changes. We run systems we built years ago.
What we work with
Most of what we build, we still run.
Reactll built Estimonia's AI-powered antique valuation platform from the ground up — combining full-stack development, computer vision integration, and a comprehensive SEO content strategy that drove 25+ guides to first-page rankings within six months of launch.
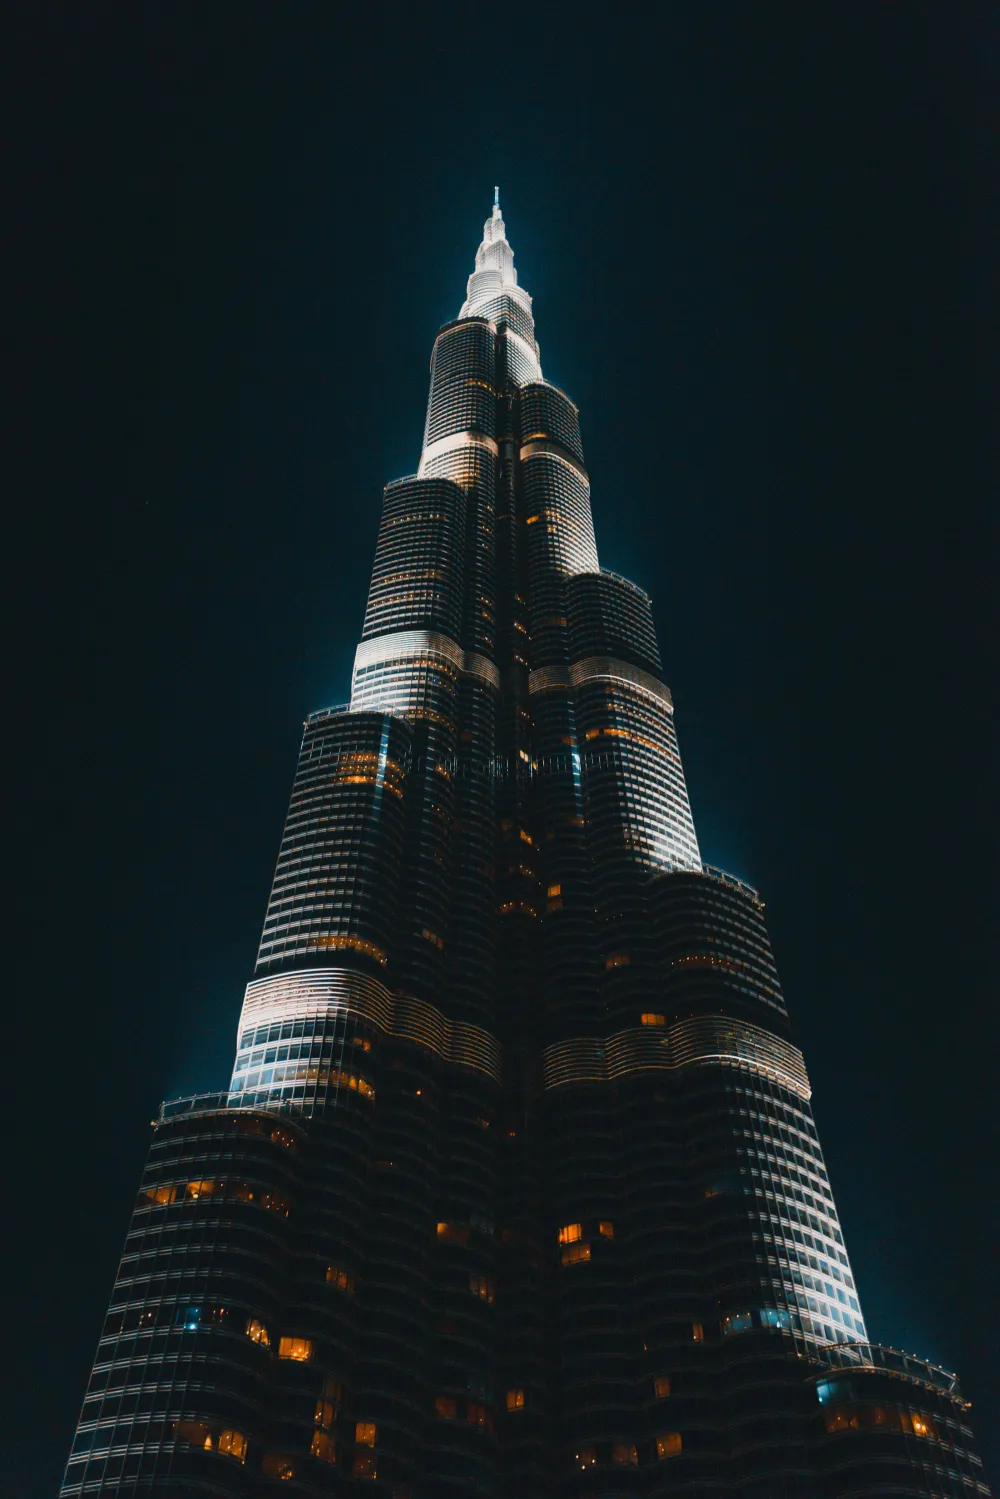
See our workReactll designed and developed a comprehensive community platform for Real Estate Club Dubai, connecting agents, investors, and property professionals across the UAE. Through custom Laravel/Livewire development, interactive calculators, and aggressive SEO, the platform grew to 79+ active members and 948 discussions.
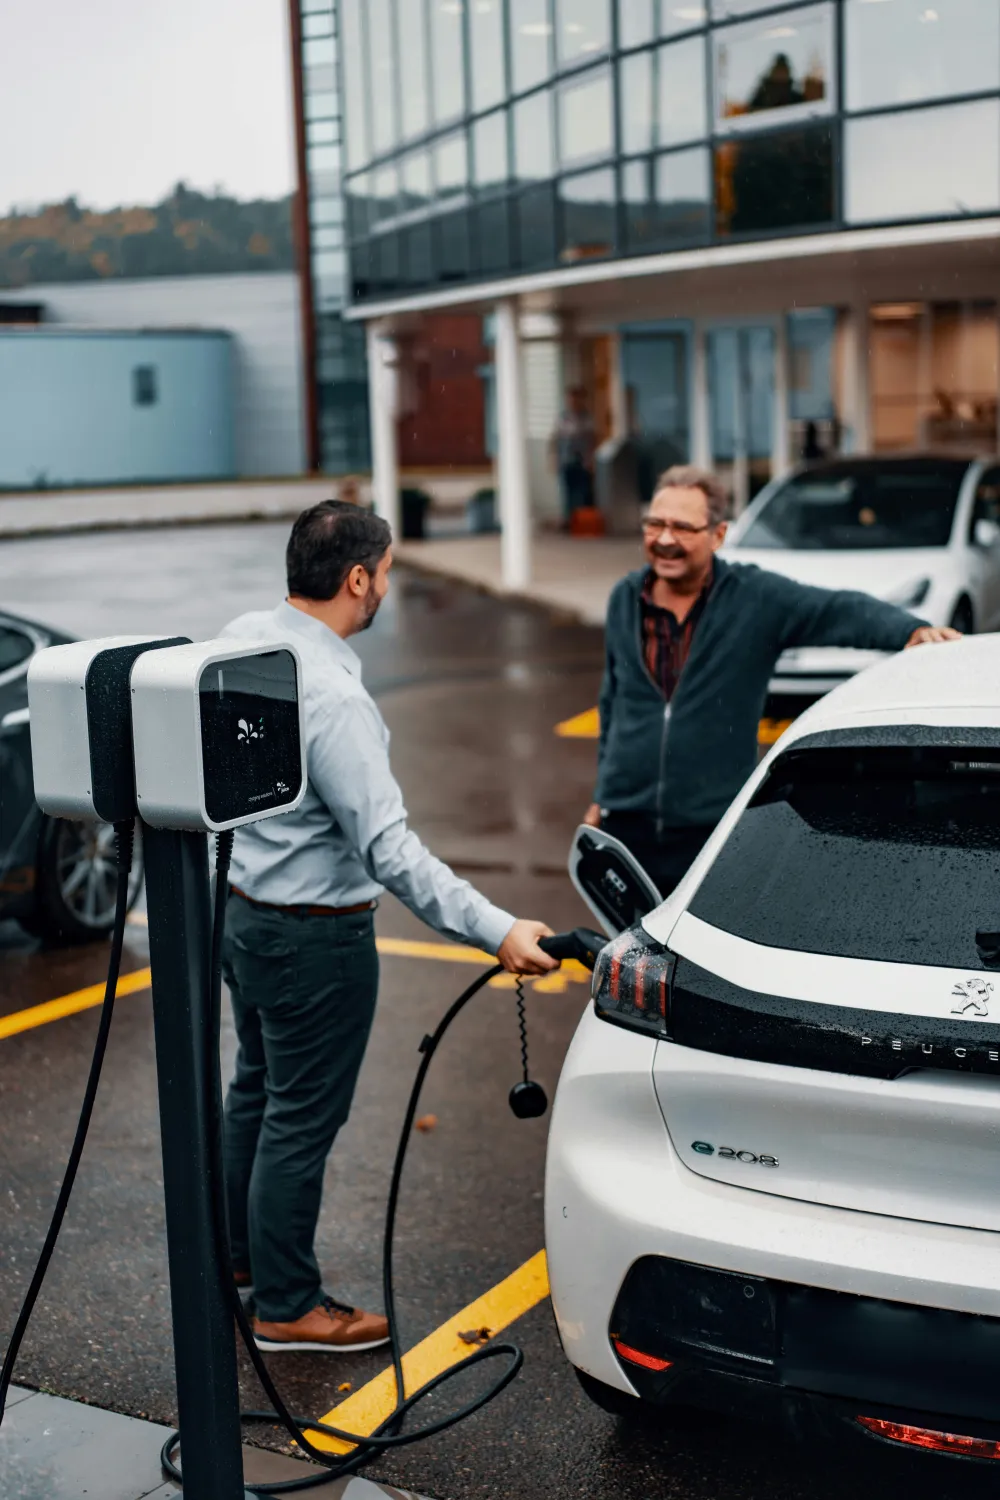
See our workWe built CheapEVCharger from the ground up as a comprehensive EV charging comparison and education platform. With 50+ charger reviews, 6 interactive calculators, and a programmatic SEO strategy, the platform now serves 10,000+ monthly EV owners.
See our workPick the smallest step that answers your question.
Each one ends in something you can look at — working output, not a proposal. Start where the risk is, not where the roadmap says.
Talk to an engineerWe look at the workflow, the data behind it and the systems it touches, then tell you what is buildable, what is not, and what it will cost to run each month. You get a written technical plan you can take to anyone, including another supplier.
One workflow taken from nothing to running in production with real users. Deployment, monitoring, evaluation and handover documentation are part of the scope, not a later phase.
We operate the system, watch quality and cost, keep it current as providers change, and build the next workflow on the same foundation. This is how most of our AI work continues after the first system ships.
Questions we get asked.
How we scope the work, what it costs to begin, where your data lives, which model or stack we reach for, and who actually does the building. If yours is not here, it is one message away.
Ask an engineerNo. We build systems on top of hosted models from Anthropic, OpenAI and Google Vertex AI. Training a model from scratch is almost never the reason a business problem is unsolved, and we will say so if we think custom training is genuinely required.
Your data stays in your systems. Retrieval happens against your own storage, and only the context needed to answer a specific request is sent to the model provider. We agree the data boundary in writing before we build, and we can restrict which providers and regions are used.
It depends on the task, the latency you need and what you are willing to spend per request. We design so the model is a replaceable component, because the right choice changes every few months and you should not have to rebuild when it does.
By designing for it rather than hoping it away. We constrain output formats, ground answers in your own data with citations, run evaluation sets against changes, and route low-confidence cases to a person. Where a wrong answer would be expensive, the system asks rather than guesses.
Yes, and it usually works better that way. We build in your repositories, follow your review process, and document the system so your team can maintain it. If you want us to hand over completely at the end, we plan for that from the first week.